Reading speed (prefill)
Measured in tok/s
How fast the model takes in everything you send: your prompt, files, an app’s instructions and the conversation so far. It sets how long big jobs wait before anything happens.
LMM is a Mac app for running local AI. It shows which models and context sizes fit your Mac, and finds the bottleneck when something slows down.
Free to download, and the menu-bar monitor is free to use. Planner, Checkup and the other tools start with a 3-day free trial on Monthly or a 7-day free trial on Annual. Already bought LMM? Download it, then enter your license in the app, or recover your license by email. For Macs with Apple silicon and macOS 14 or later.
LMM menu bar view showing unified memory headroom, model writing speed and Checkup findings on an M3 Max with 128 GB.
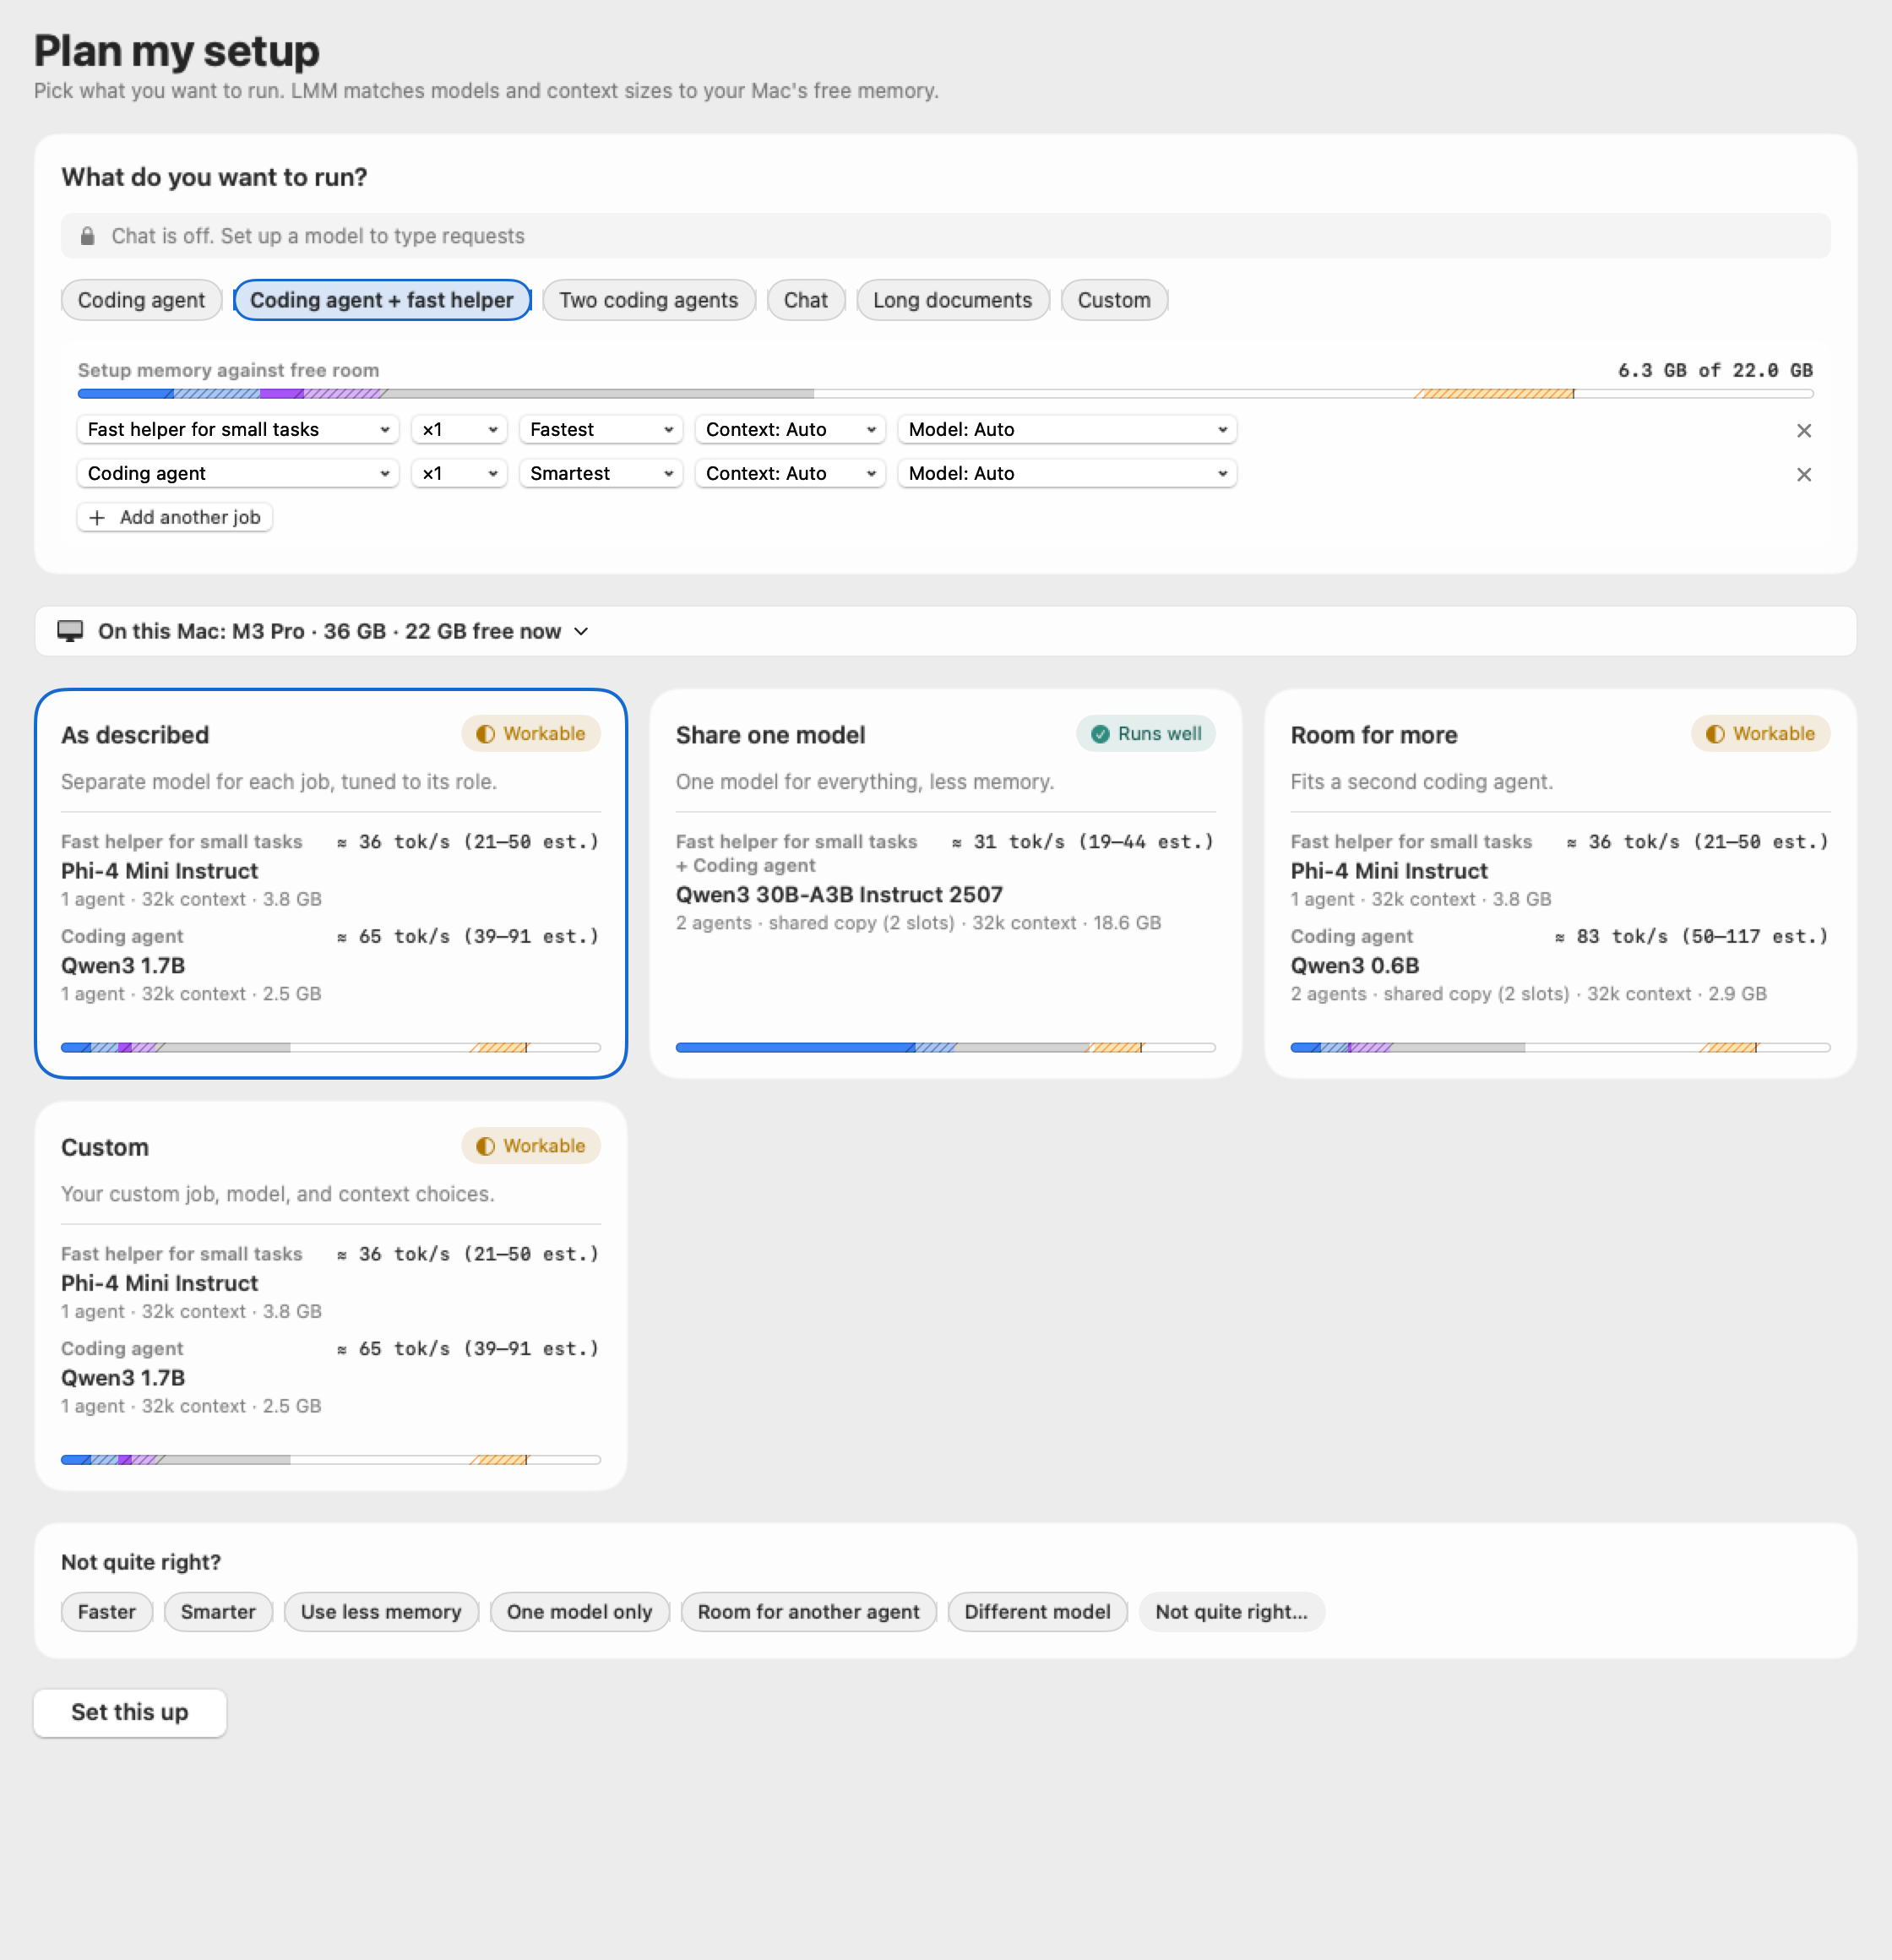
Tell LMM what you want to do. It compares the setups your Mac can run and recommends the best match for your work, balancing the task (coding, writing and more), memory use, quantization loss, unlocked models and the intelligence index.
Example requestCoding agent + fast helper on an M3 Pro with 36 GB
Most people judge local AI by one number, tokens per second. That only tells you how fast the answer is written. Before the first word appears, the model has to read everything you sent, and for a coding agent that can be 30,000 tokens or more.
Measured in tok/s
How fast the model takes in everything you send: your prompt, files, an app’s instructions and the conversation so far. It sets how long big jobs wait before anything happens.
Measured in seconds
The pause before the answer starts. It’s mostly reading time, so it grows with long prompts, big files and long conversations.
Measured in tok/s
How fast the answer appears once it starts. It’s the number most people quote, but once it outpaces your reading, the wait for the first word matters more.
TokenA short word or part of one. 1,000 tokens is roughly 750 English words.
Every model needs memory for itself, and more for its context window, the limit most apps hide. Pick your Mac and find a model: you’ll see the memory it needs, the context it can hold and how fast it should write. The app runs the same check against your Mac’s real memory.
No model in the catalog matches that search yet.
One scan looks at memory, running models, connected apps and server settings. Each finding explains itself before anything changes.
Frees 26 GB of memoryFixes 1 context problem
118kof 128k
Long sessions will start losing early files. A larger context for Qwen3 30B-A3B Instruct 2507 fits in the room you have.
26GB of memory
Unload it to free memory now, and load it again when you need it.
40GB on disk
Llama 3.3 70B is taking up disk space. Keep it for later or remove it.
Connect a cloud model you choose and LMM can walk you through the setup: install a tool, download a model, change a setting, run a test prompt. Pick a low-cost model, read its data policy in LMM first, and nothing changes until you approve it.
Optional. LMM works without a cloud model, and nothing leaves your Mac for setup unless you connect one.
Example setup plan for Qwen3 30B-A3B Instruct 2507: a low-cost cloud model marked no training proposes four steps, download the model, set the context to 64k, point Claude Code at it and run a test prompt, and nothing runs until you approve.
Local models keep everything on your Mac. Cloud models you connect show where your prompt goes before you send it. Prompts you send to models never pass through LMM’s servers. The optional Setup Assistant is the one exception: it sends your setup question through LMM’s server to OpenAI. How LMM rates privacy
Deploy a headless Mac mini or Mac Studio instance running the lmm-host daemon over mutual TLS (mTLS). Monitor unified memory headroom and see which models are loaded, from your primary Mac.
Your Macs
The Agents & Instructions Editor is a native editor for coding agent rules and system instructions. Every save is atomic and keeps a timestamped backup you can restore in one click, and each app can be pointed at its own local runtime.
Claude Code, Codex, Cursor, Aider
Safely update instruction files like CLAUDE.md, AGENTS.md, and tool rules. Writes are atomic to prevent truncated files or broken agent workflows.
Automatic version history
Every edit saves an automatic timestamped backup before writing to disk. Revert changes instantly with one click if an instruction edit causes unexpected behavior.
Continue, Goose, Open WebUI
Route each coding agent to standard local endpoints like Ollama (127.0.0.1:11434), vLLM / MLX (127.0.0.1:8000), or LM Studio (127.0.0.1:1234) without manual configuration editing.
A native Mac app that follows your system appearance. Every page shows live memory, and advanced tools stay out of the way until you open them.
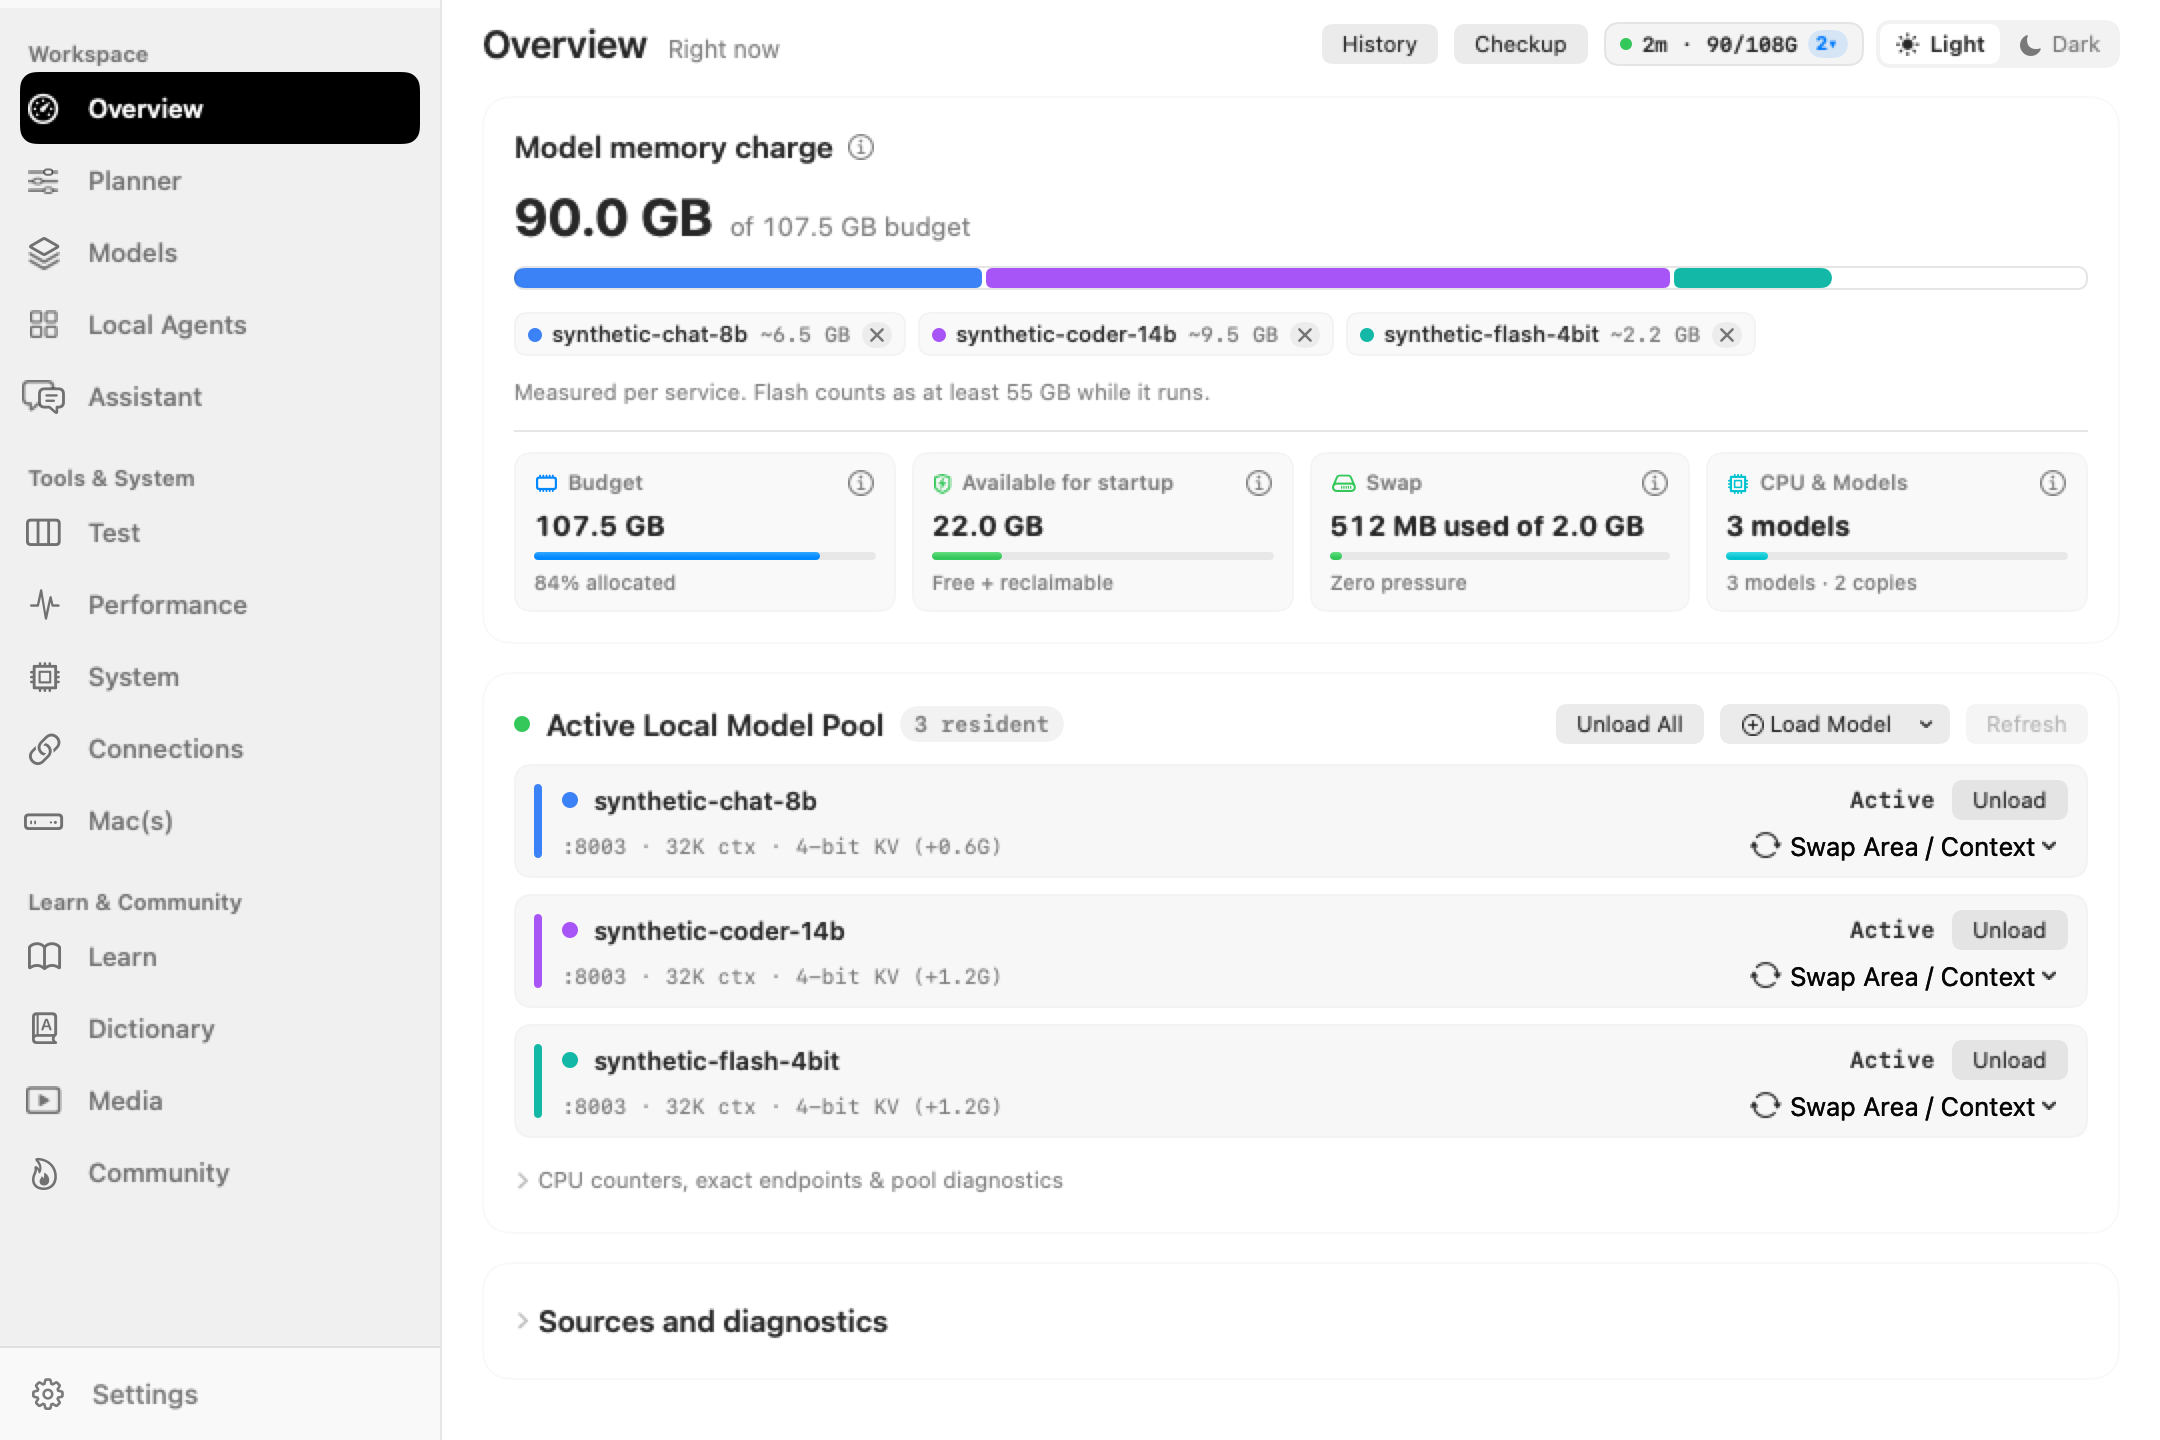
Unified memory, loaded models, system snapshot
See available unified memory, loaded models, and actionable Checkup findings in two seconds.
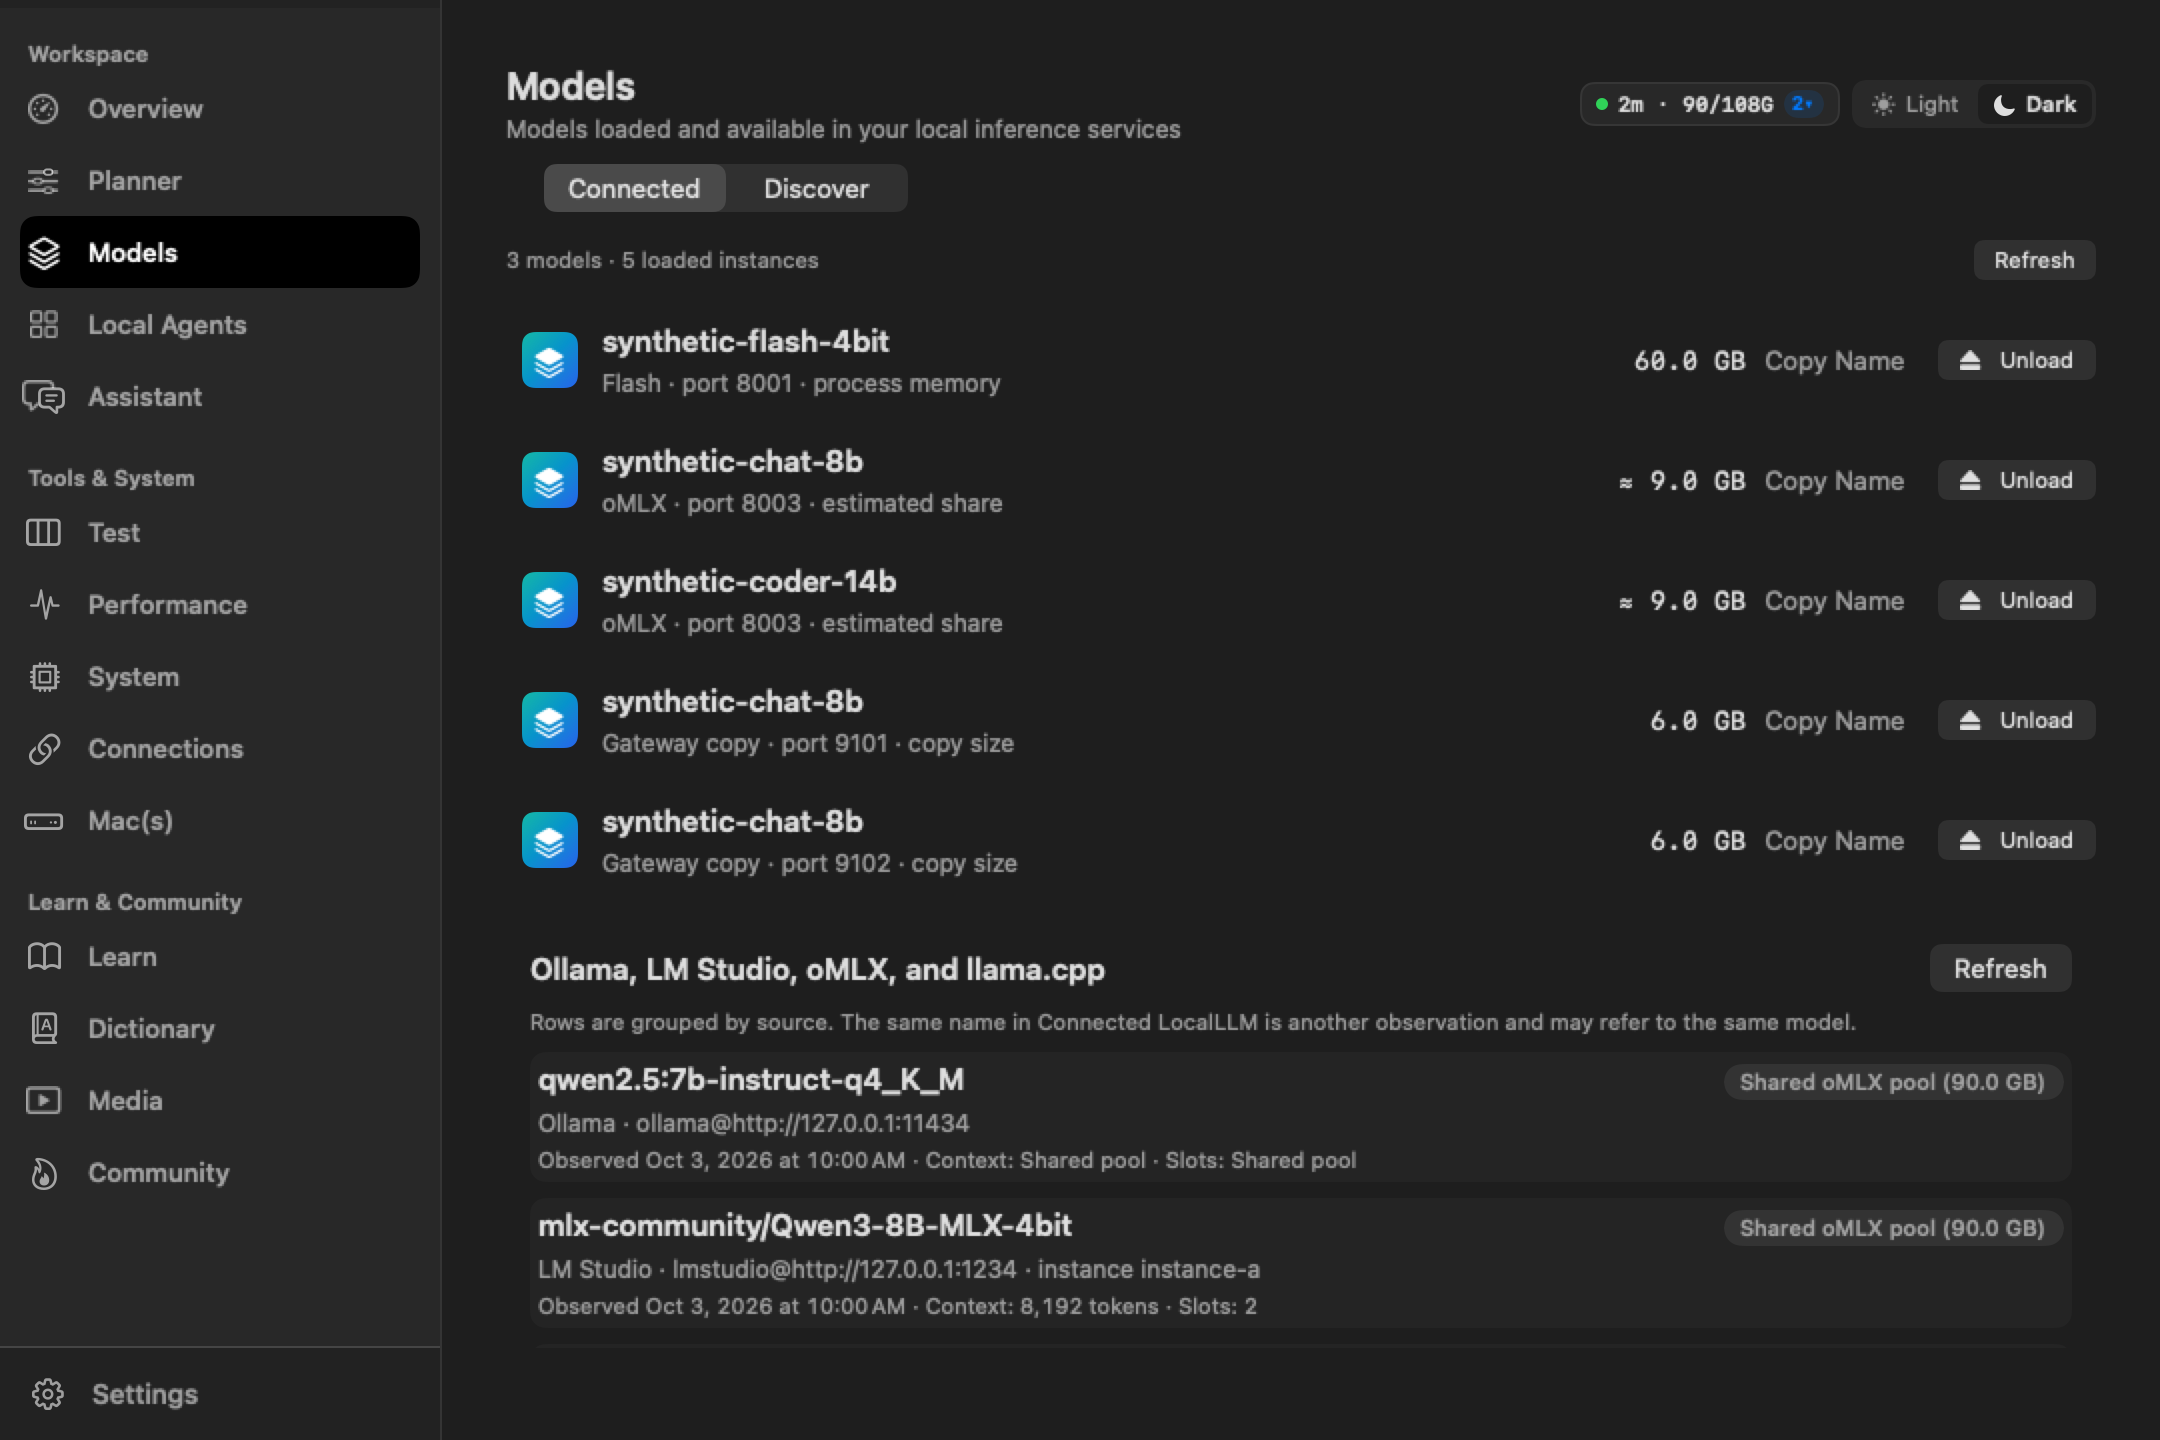
On This Mac, Discover, Paired Macs
Filter verified MLX, GGUF, and Ollama models by capability with instant Apple silicon hardware fit ratings.
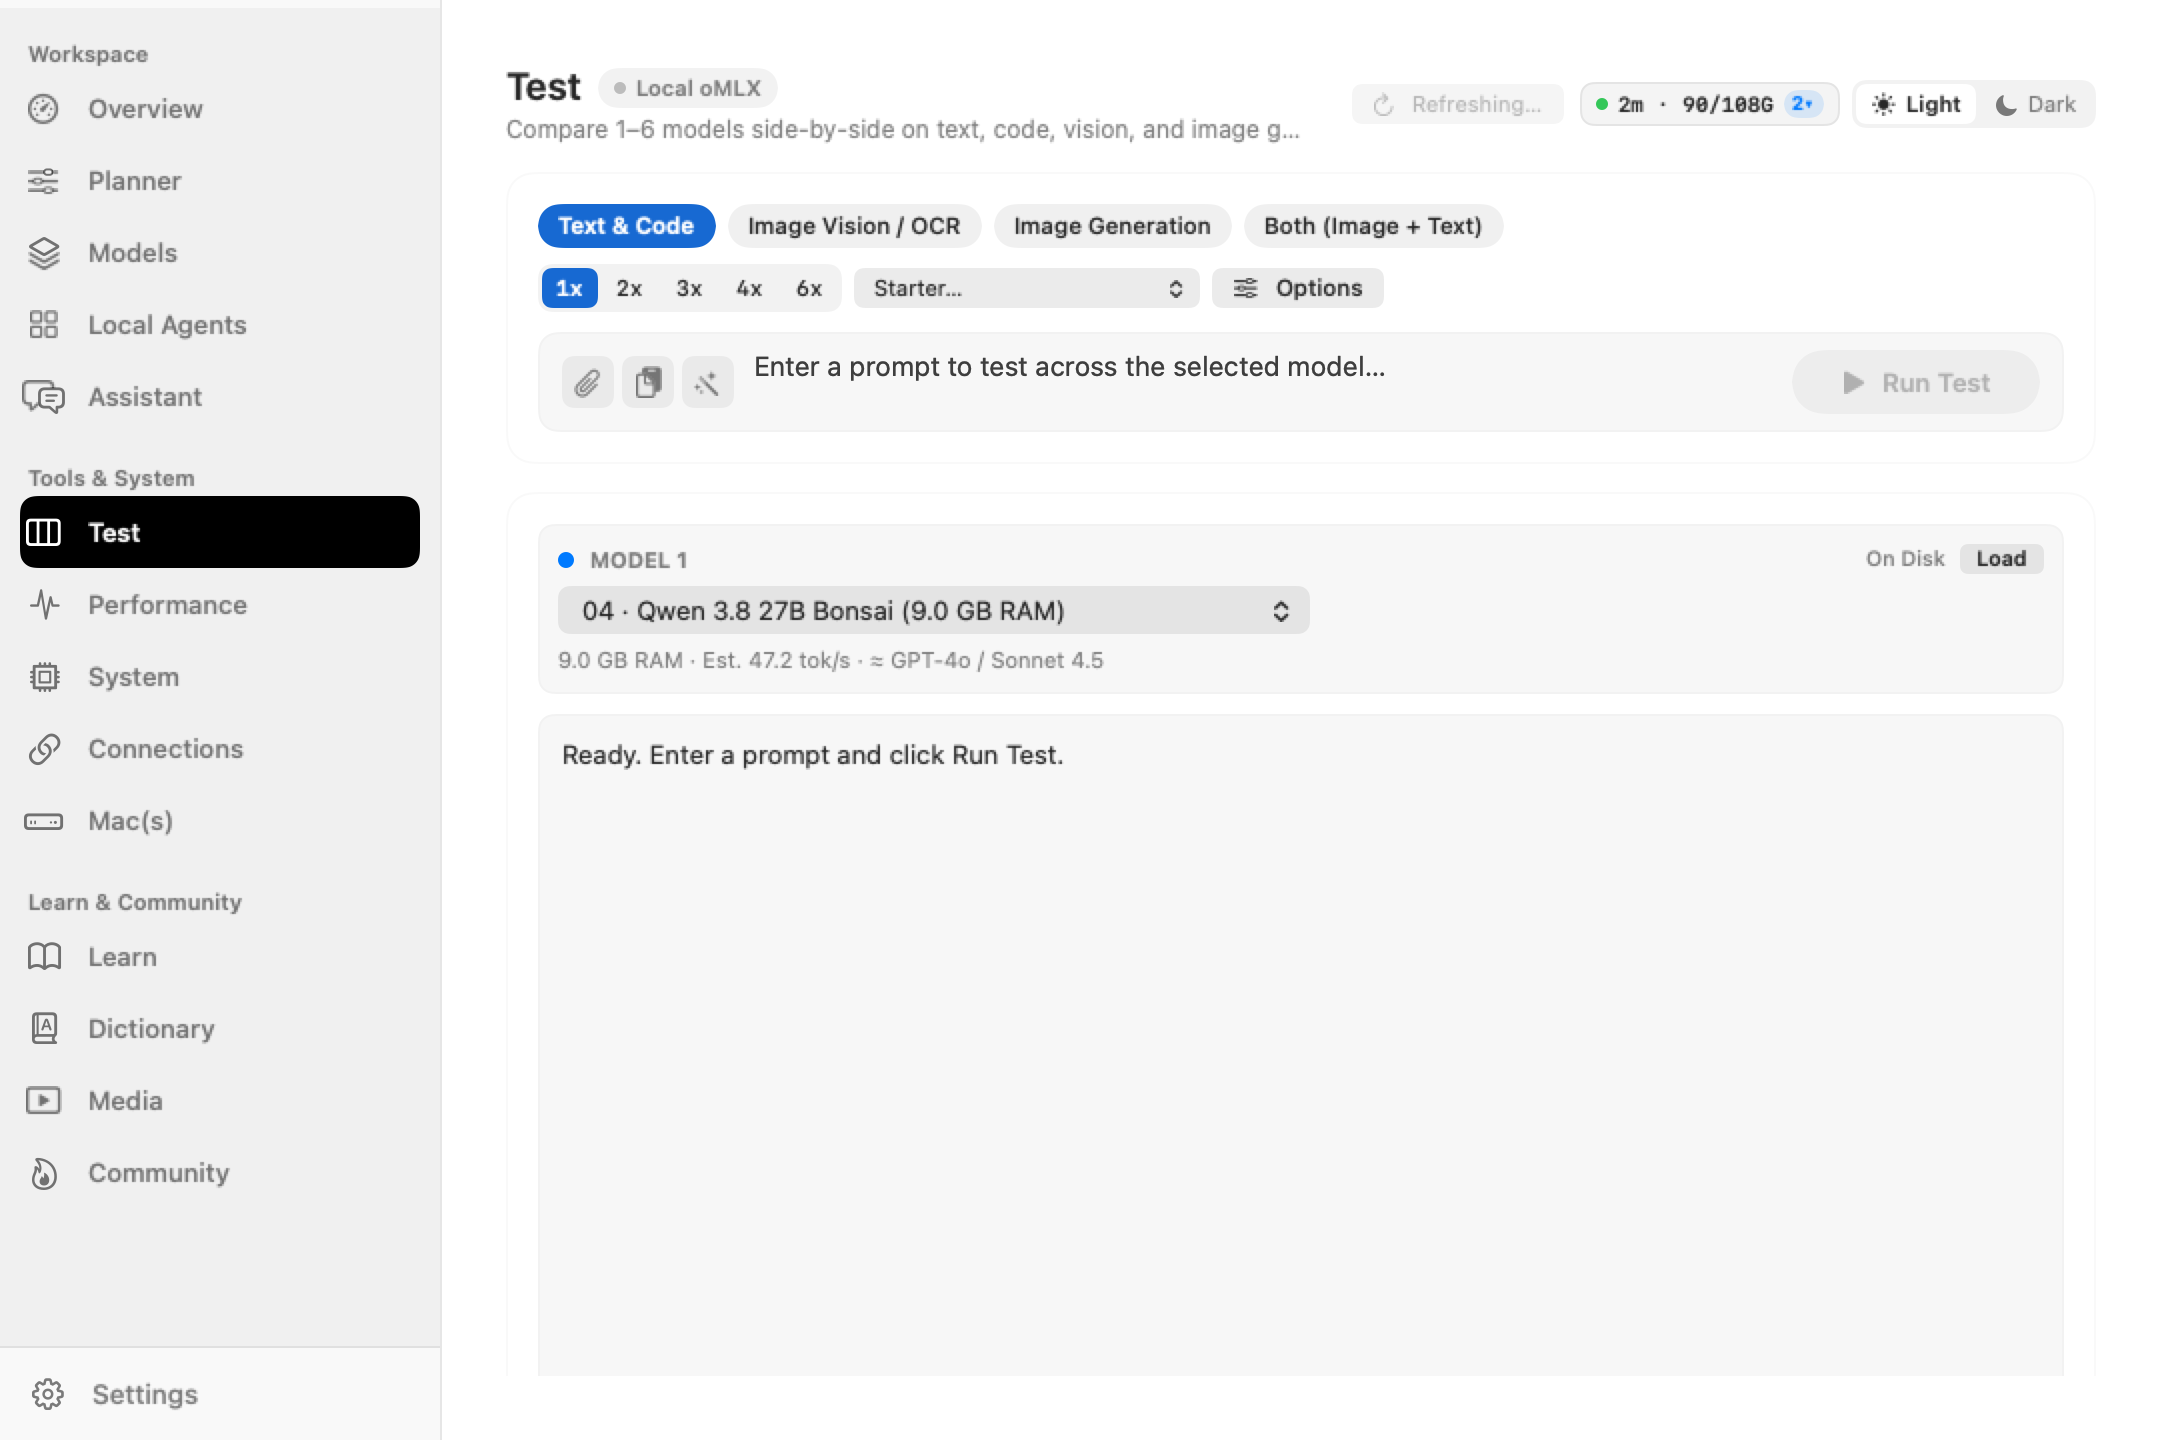
1–3 models, side-by-side compare, speed metrics
Compare up to three local or cloud models simultaneously with live prefill, first-token, and decode speed telemetry.
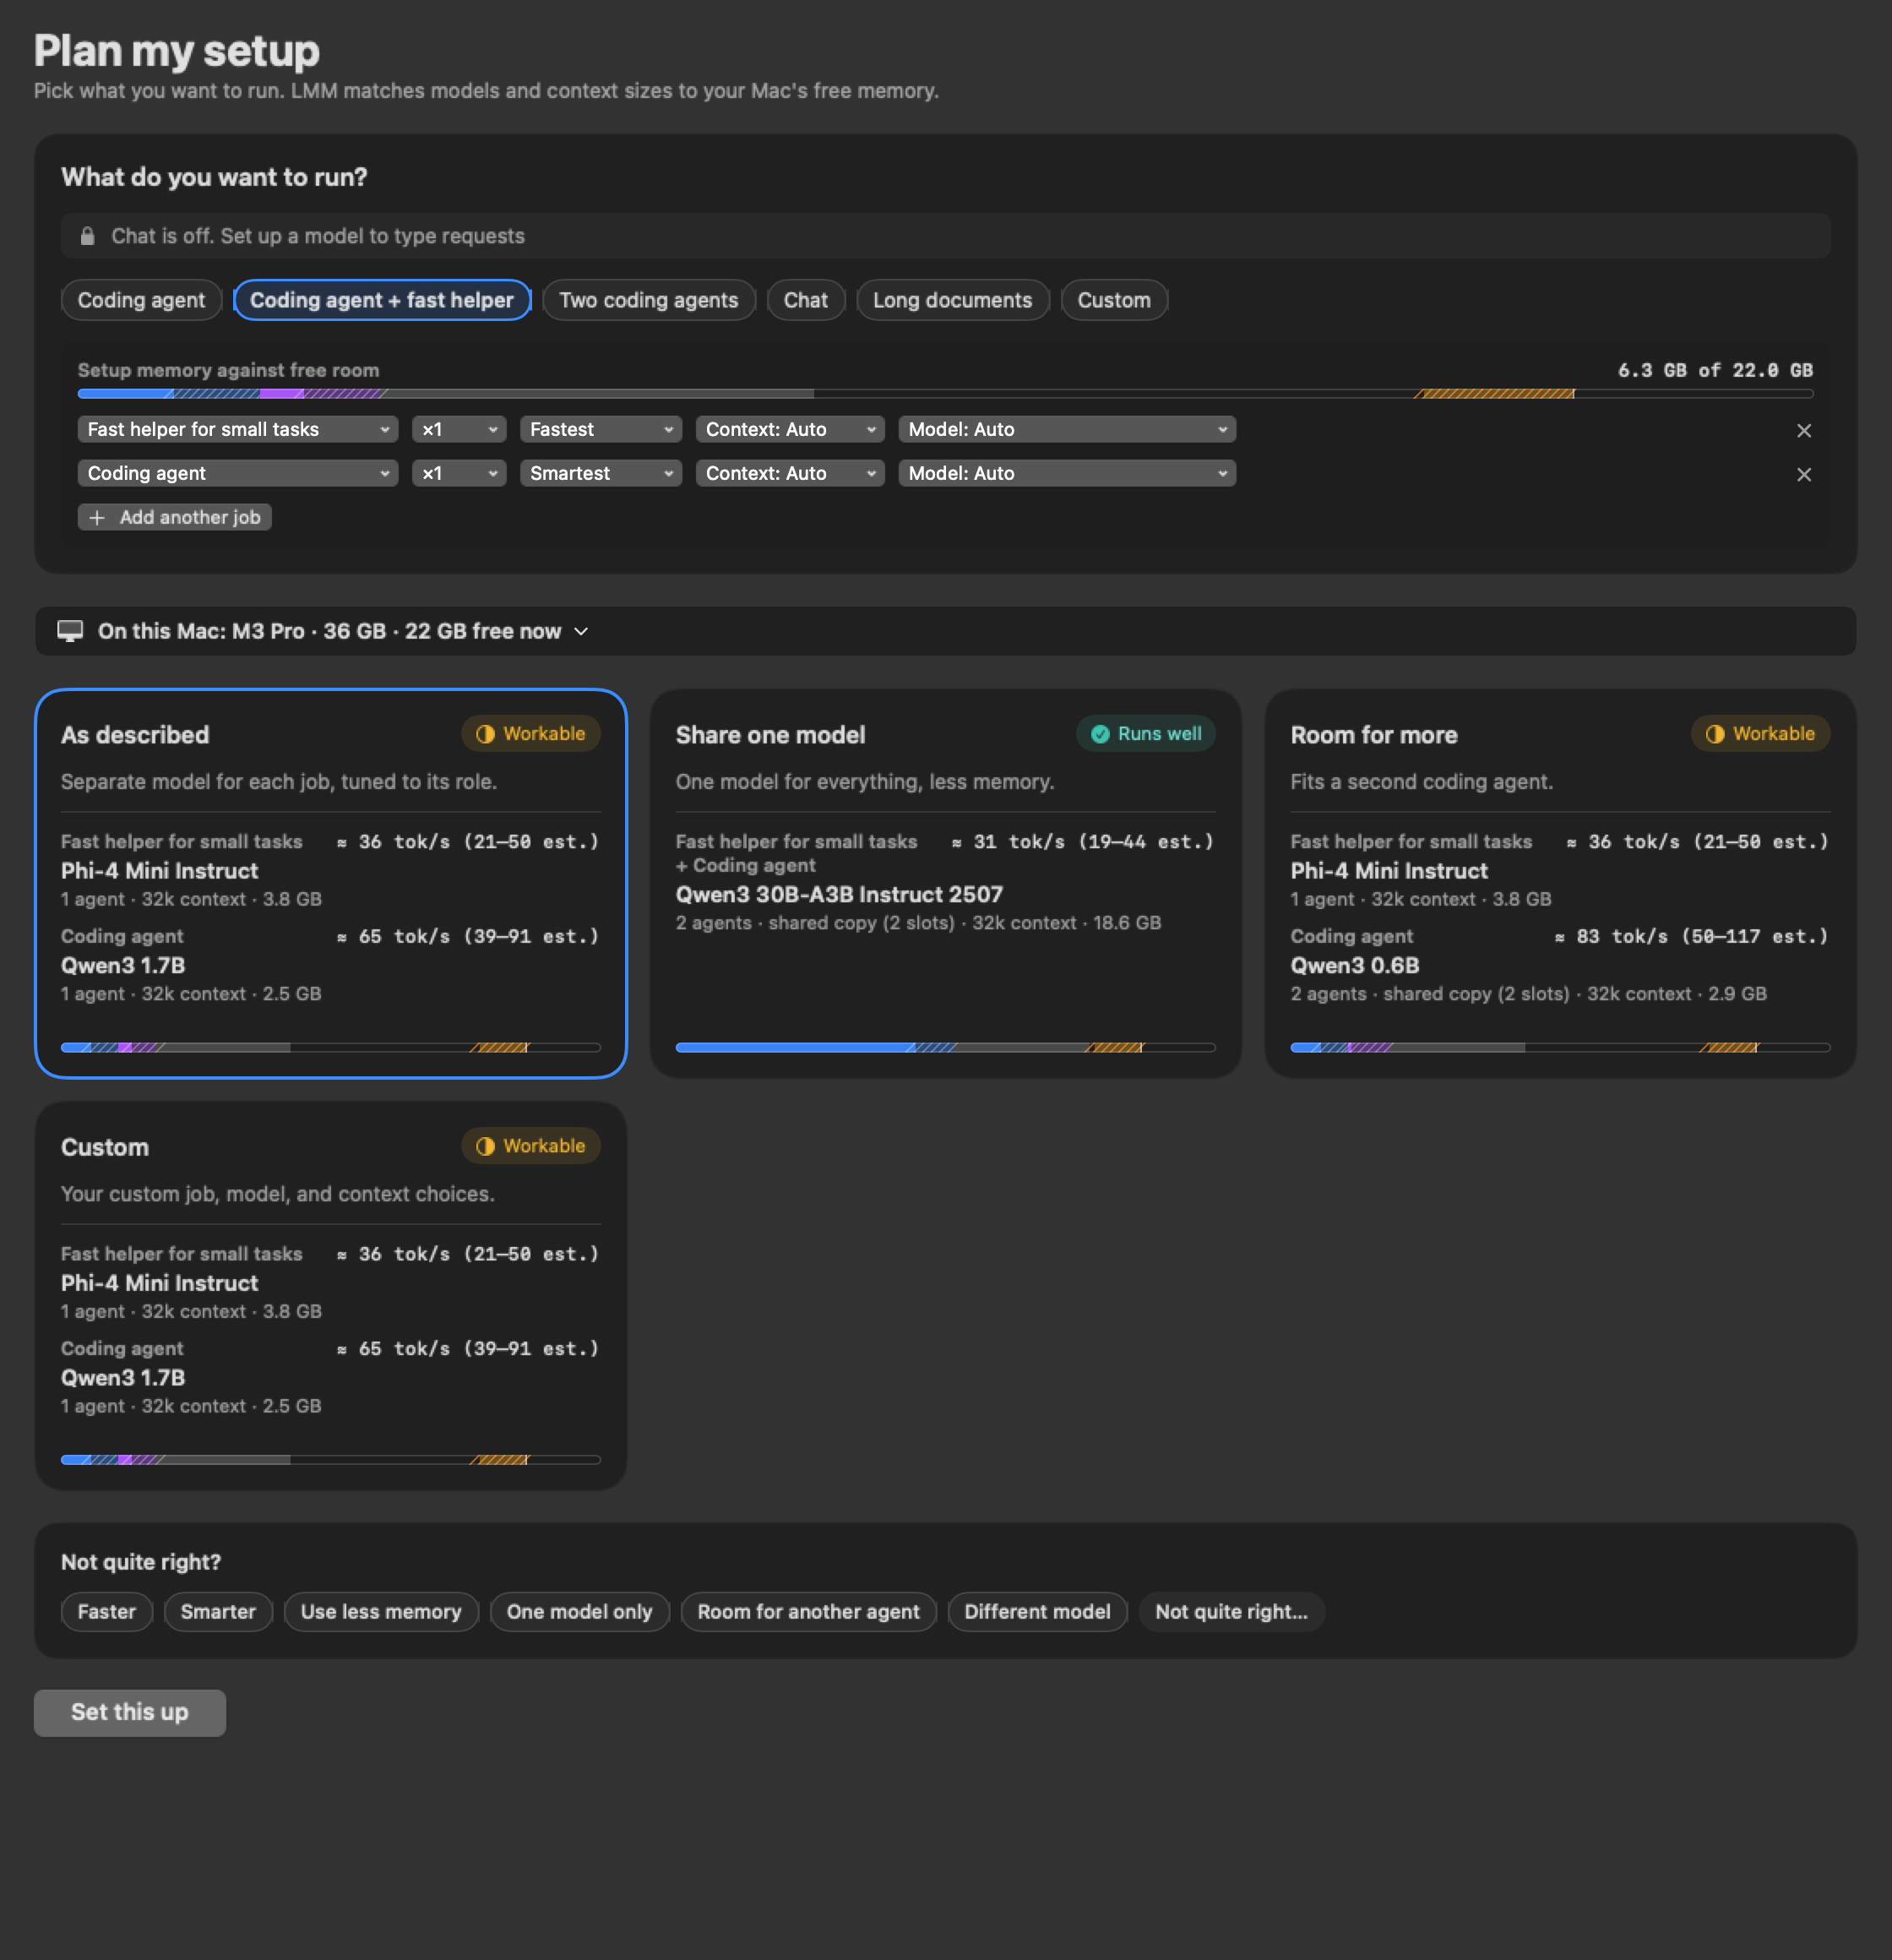
M1 or later, context sizing
Match models and context sizes to your Mac’s free memory for one or more jobs before loading.
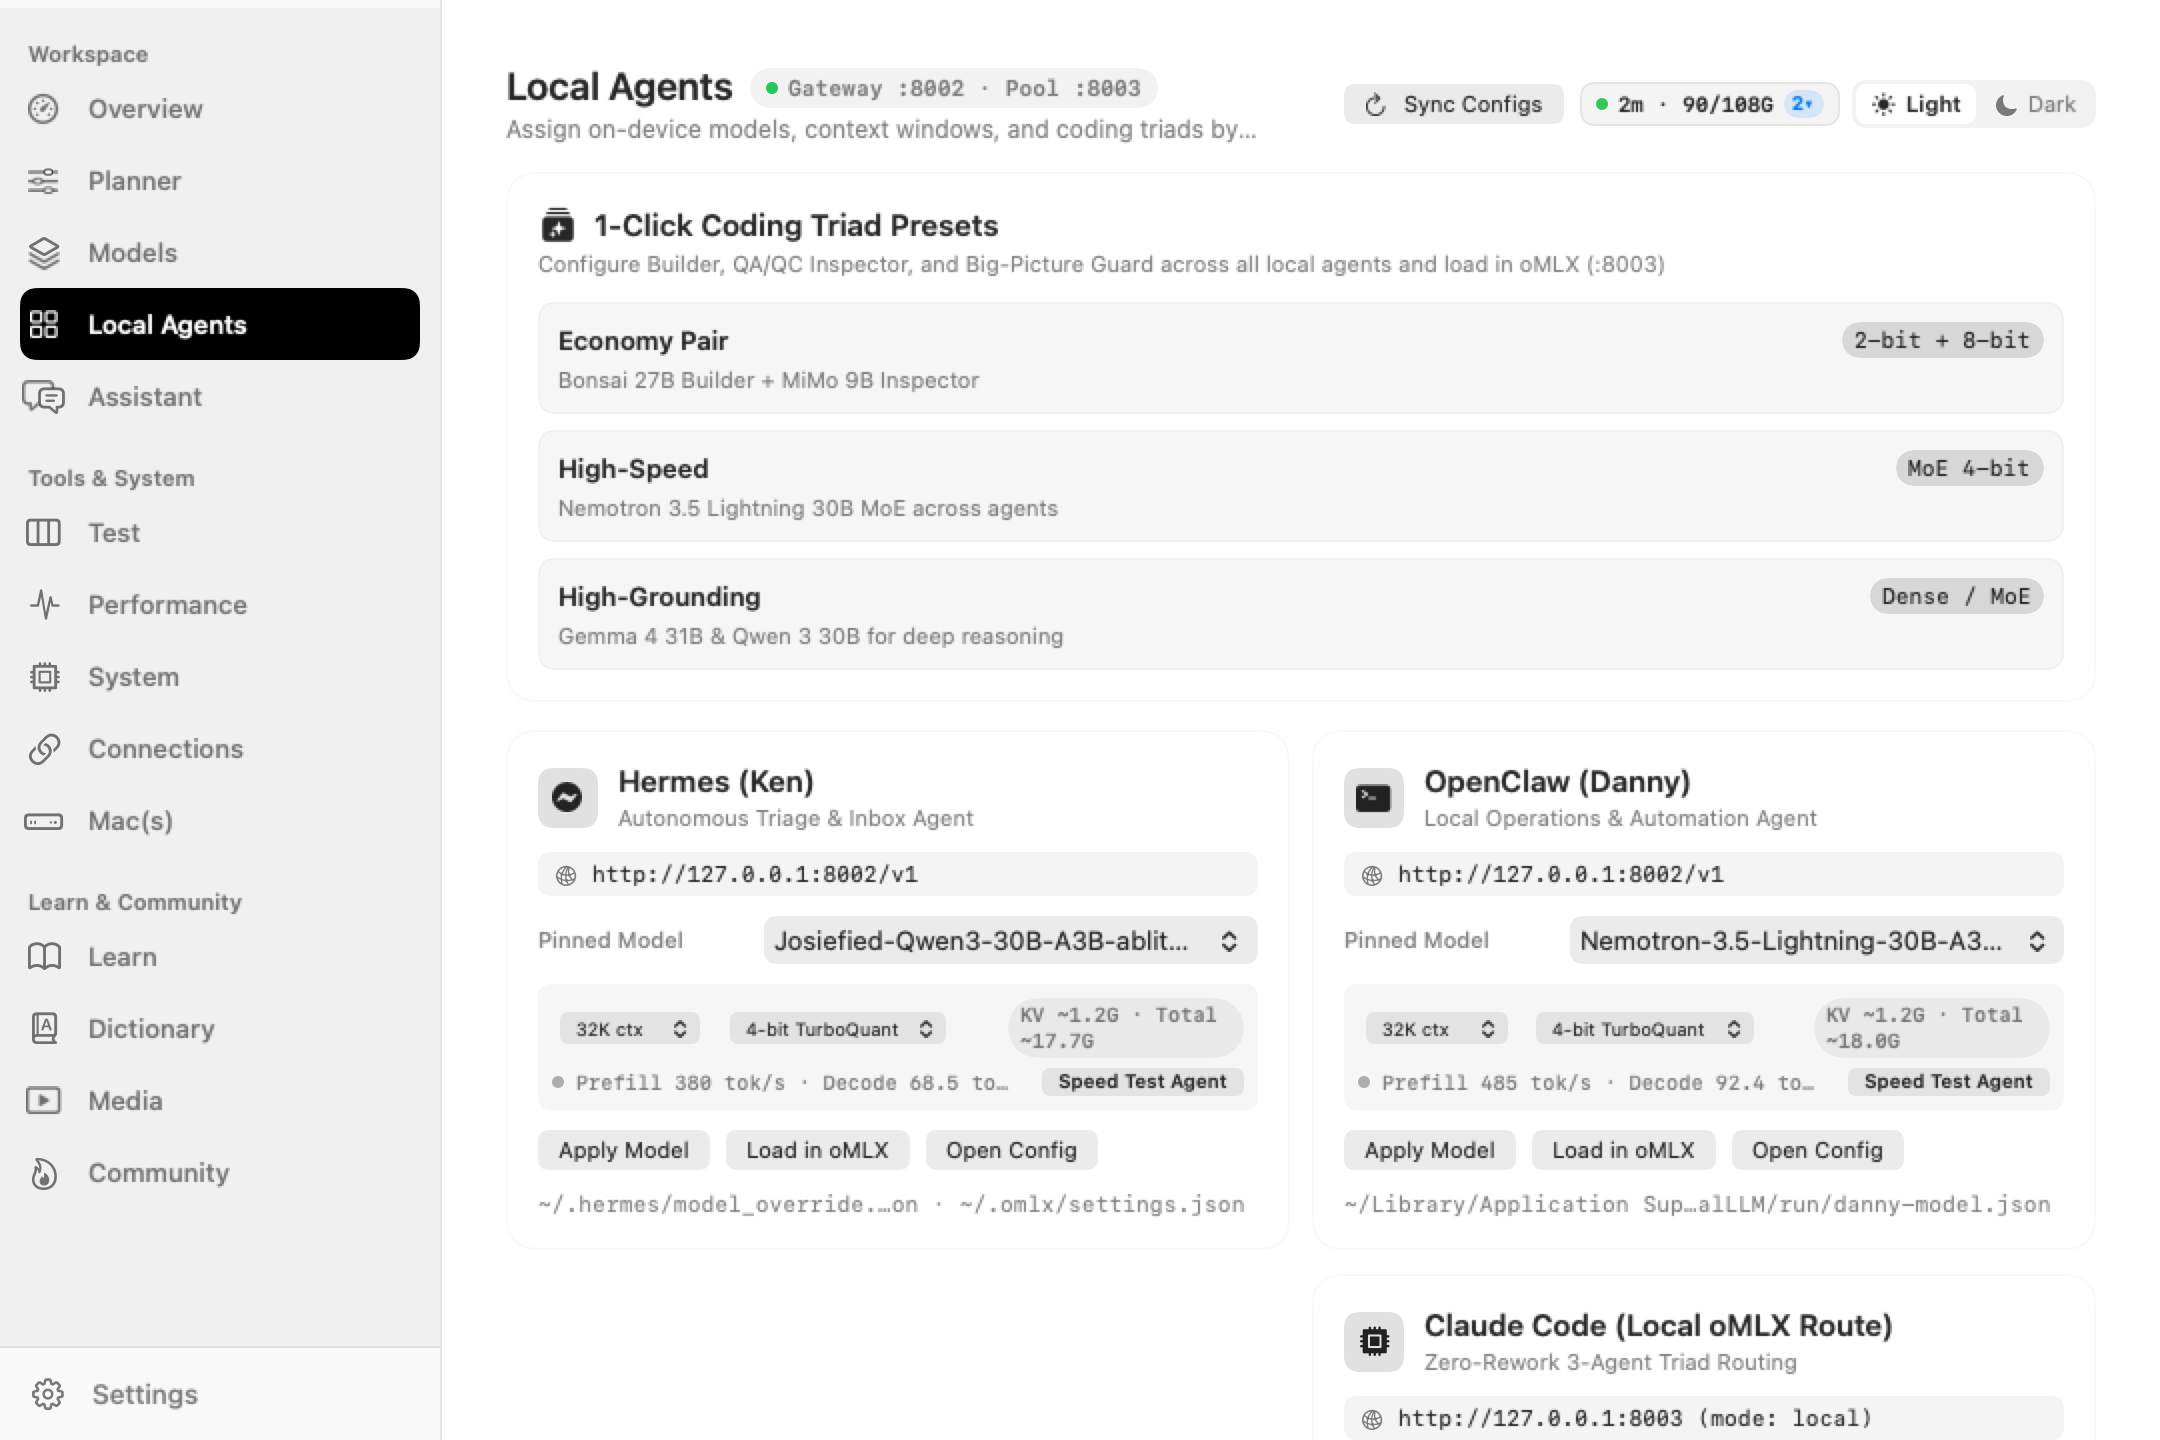
Claude Code, Codex, Goose, Hermes, OpenClaw
Bind local coding agents to your local model server in one click with automatic timestamped configuration backups and rollback protection.
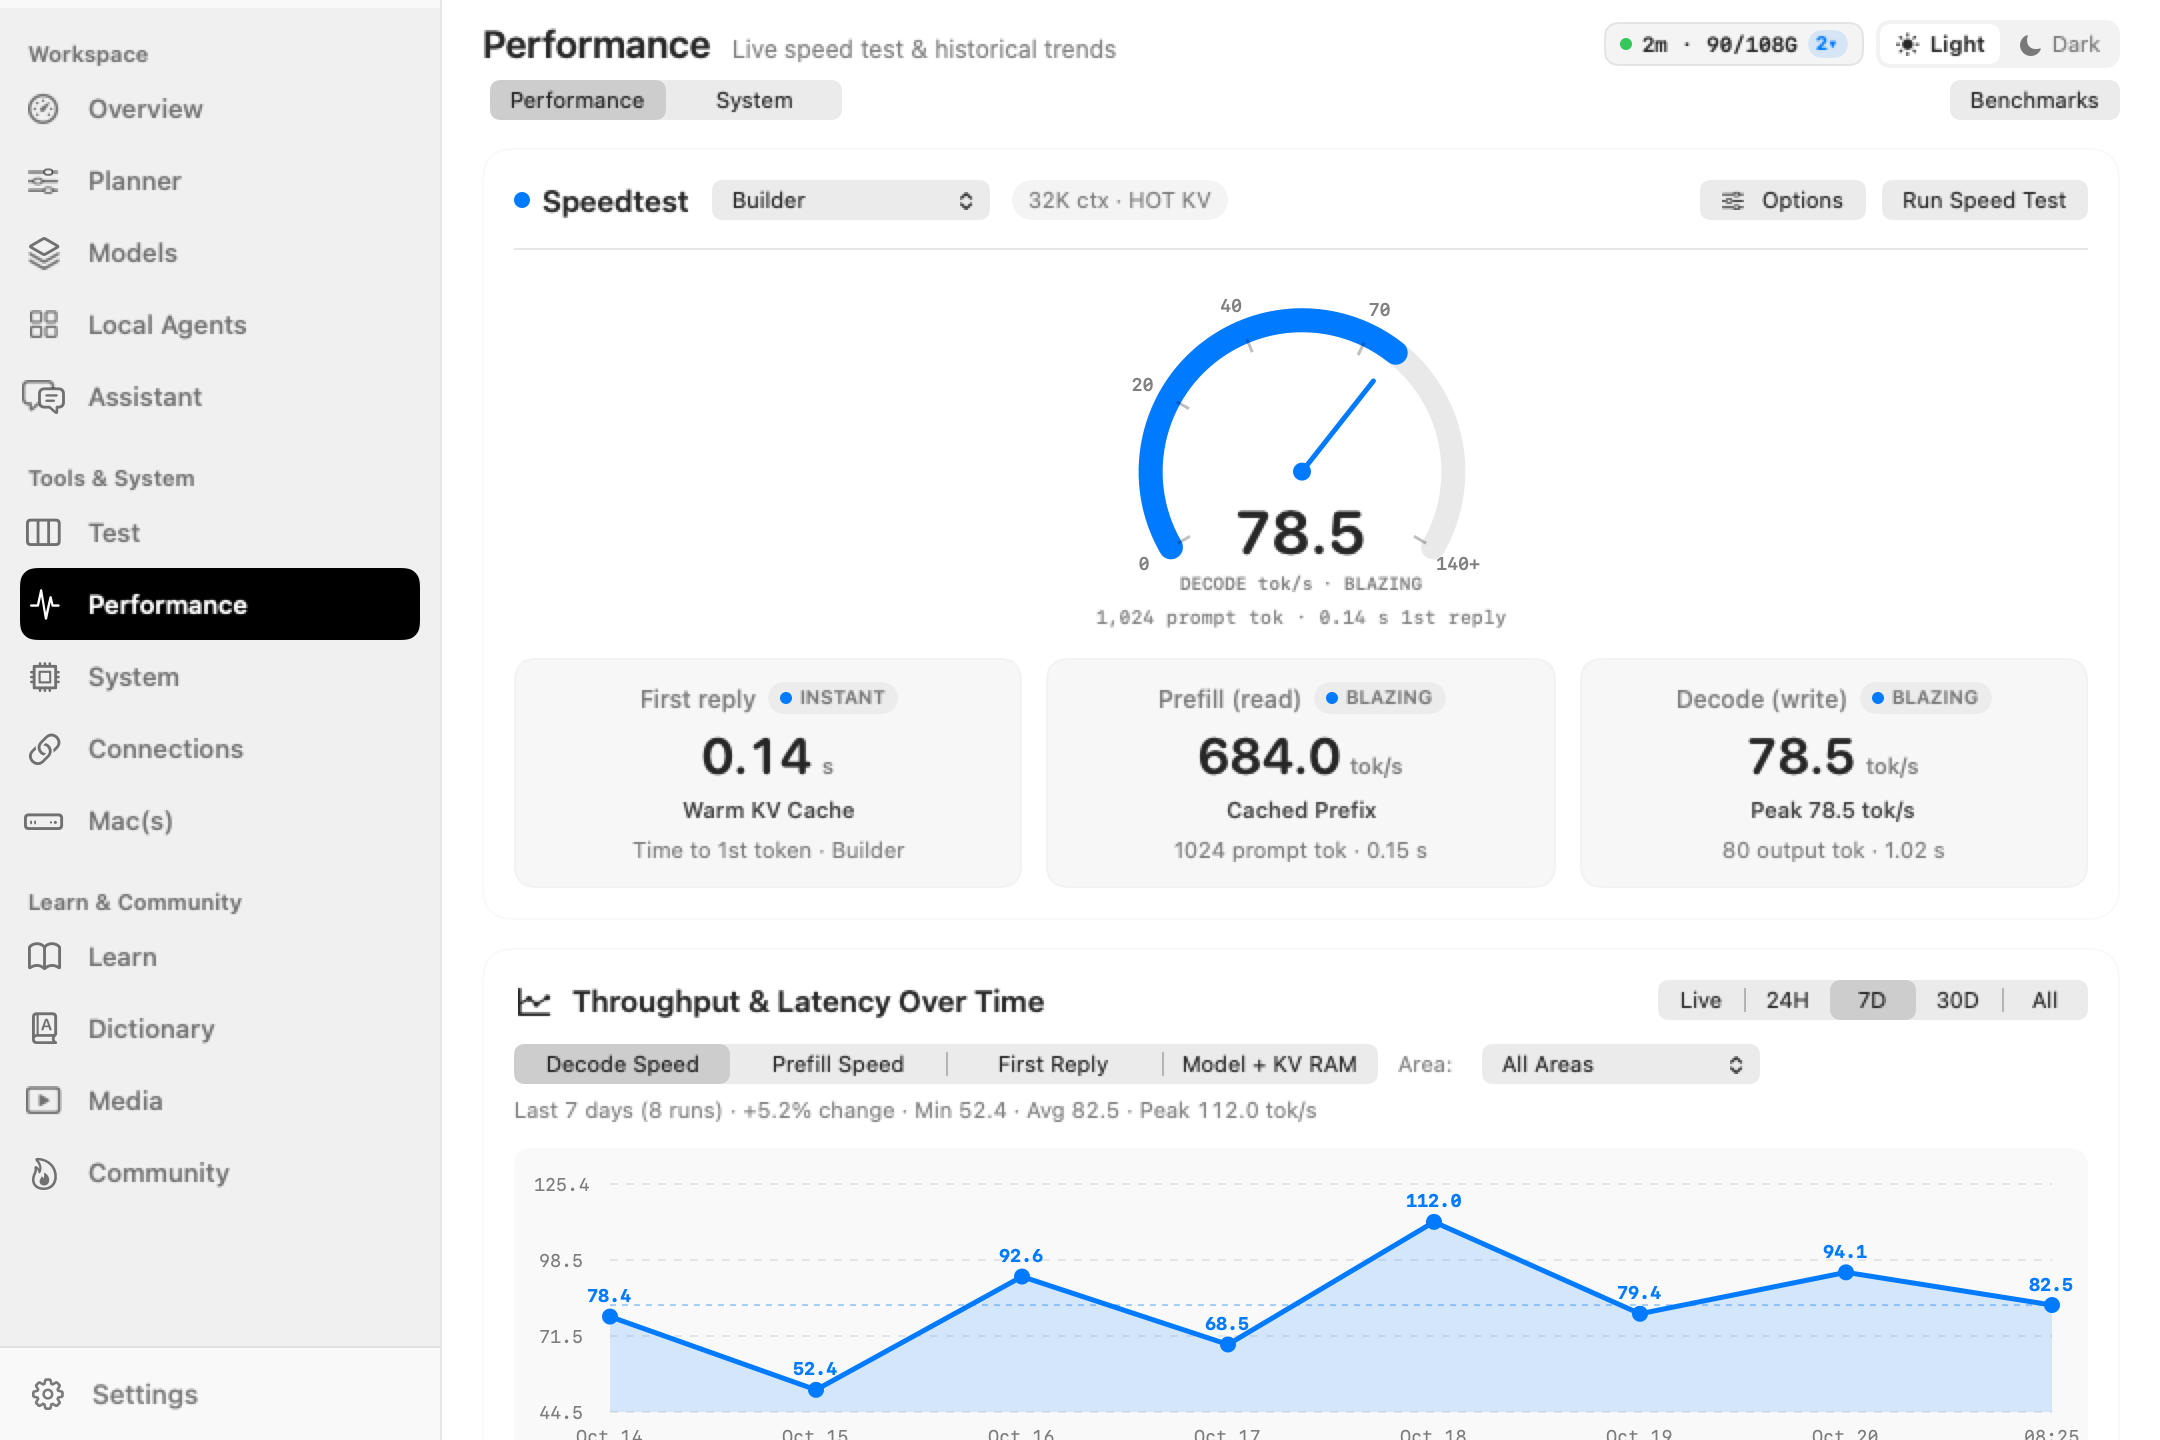
Real-time throughput, thermal and swap watch
Inspect live decode tok/s, prefill latency, and unified memory pressure across this Mac and paired headless instances.
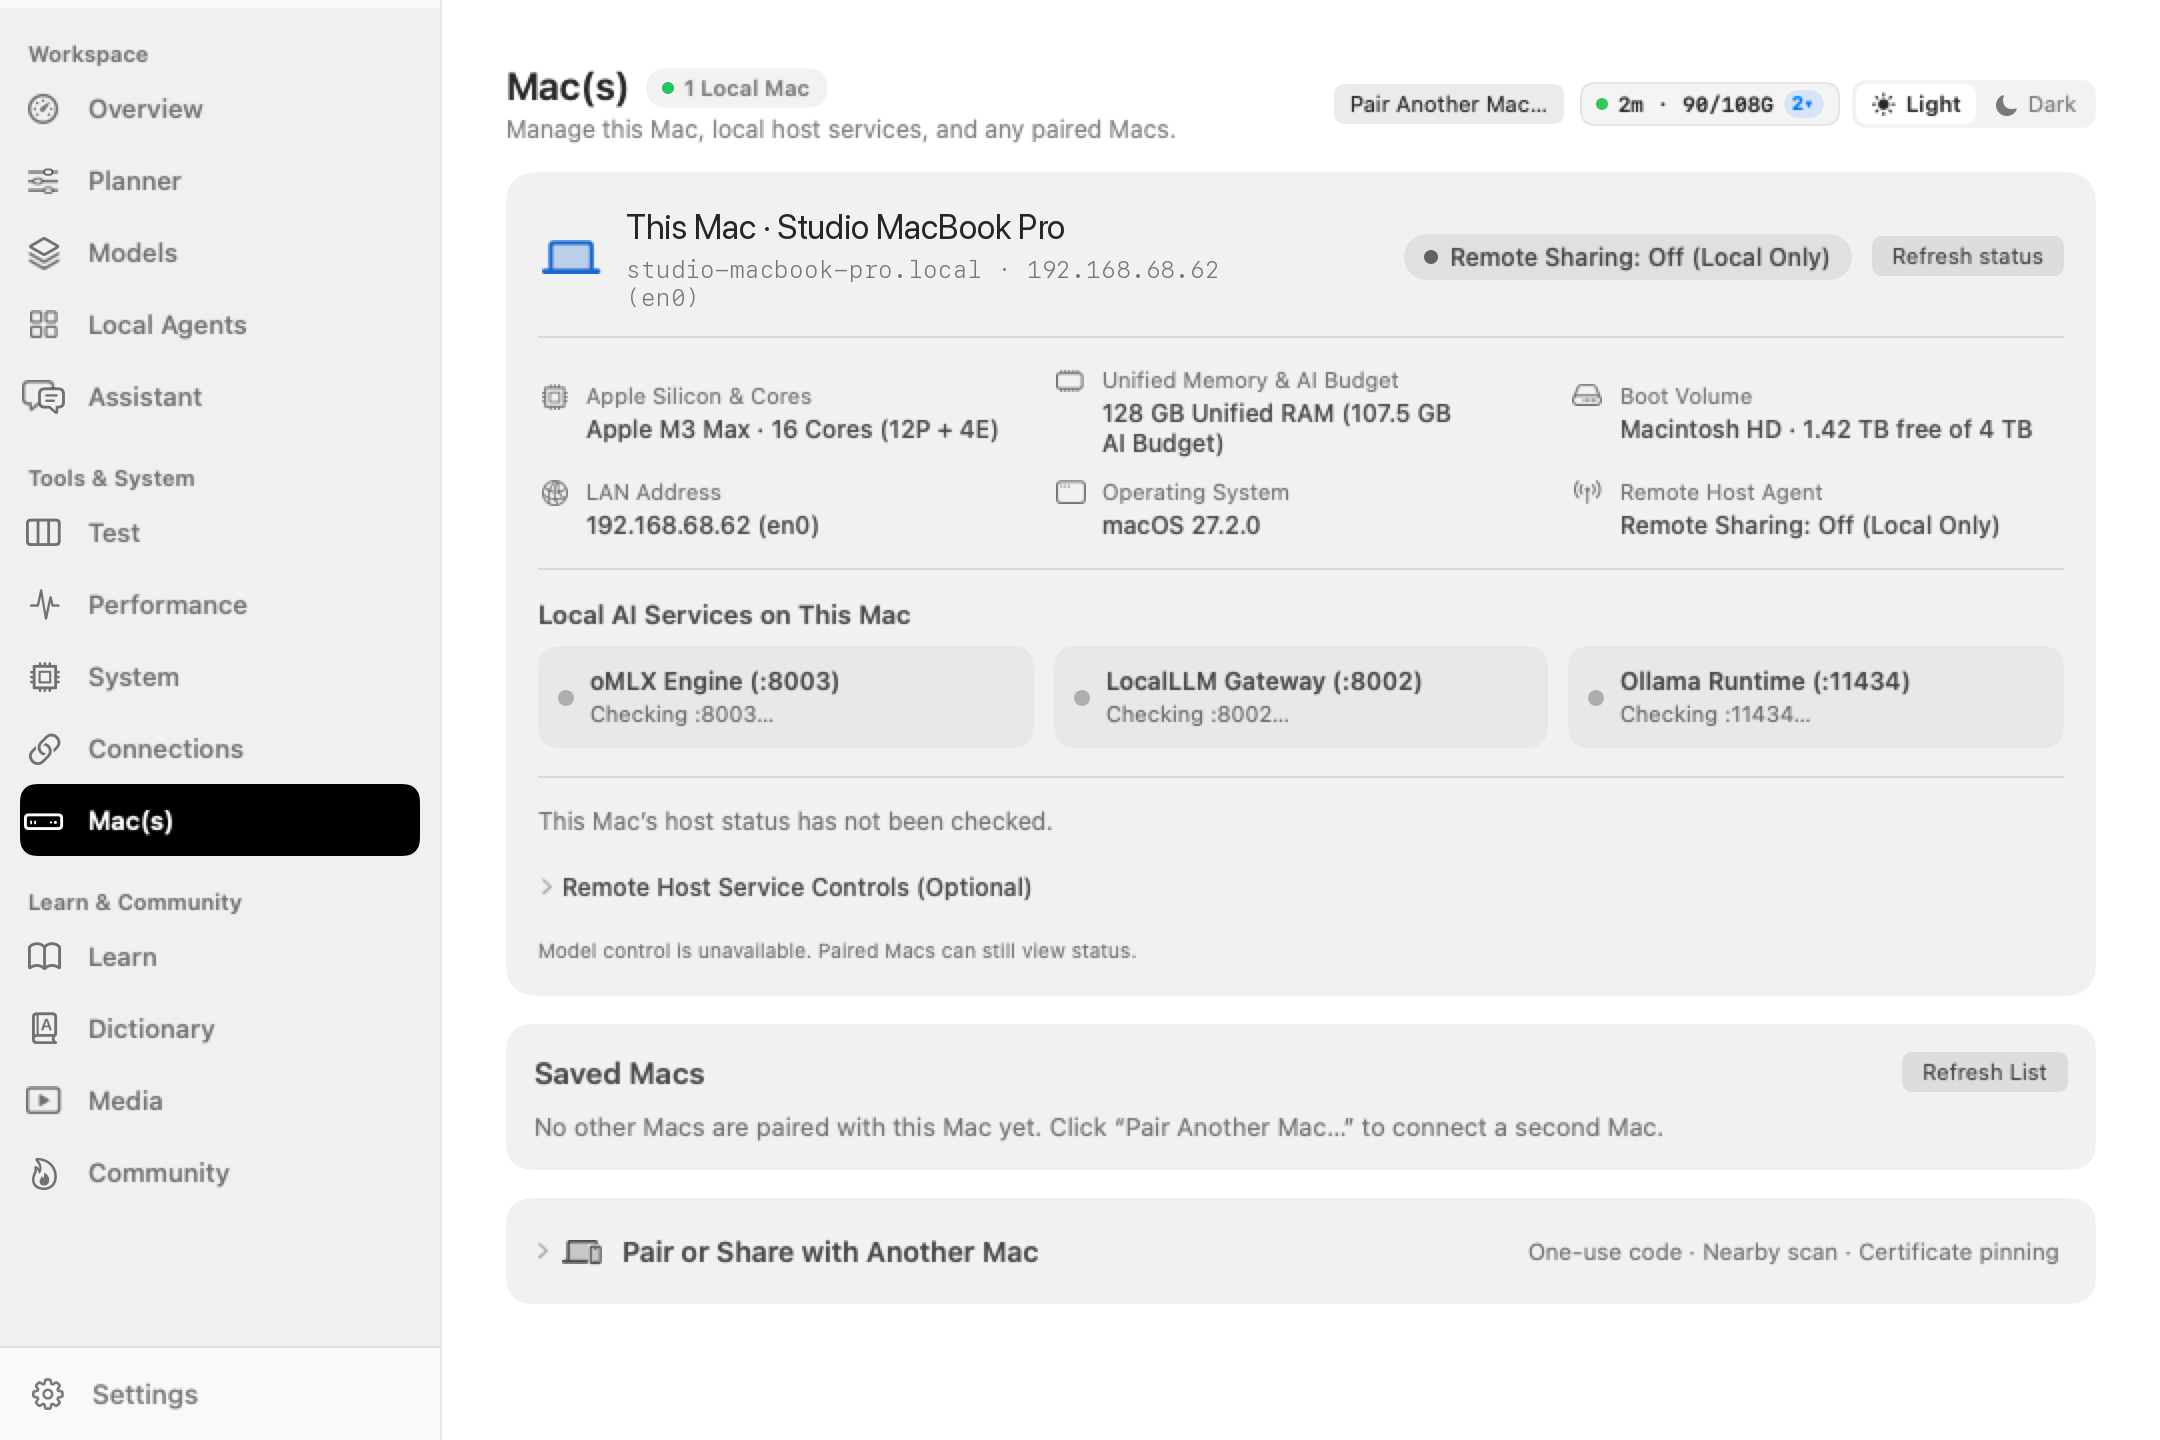
lmm-host daemon, mutual TLS, Bonjour and Tailscale
Pair headless Mac mini and Mac Studio instances over mutual TLS to monitor memory and loaded models.
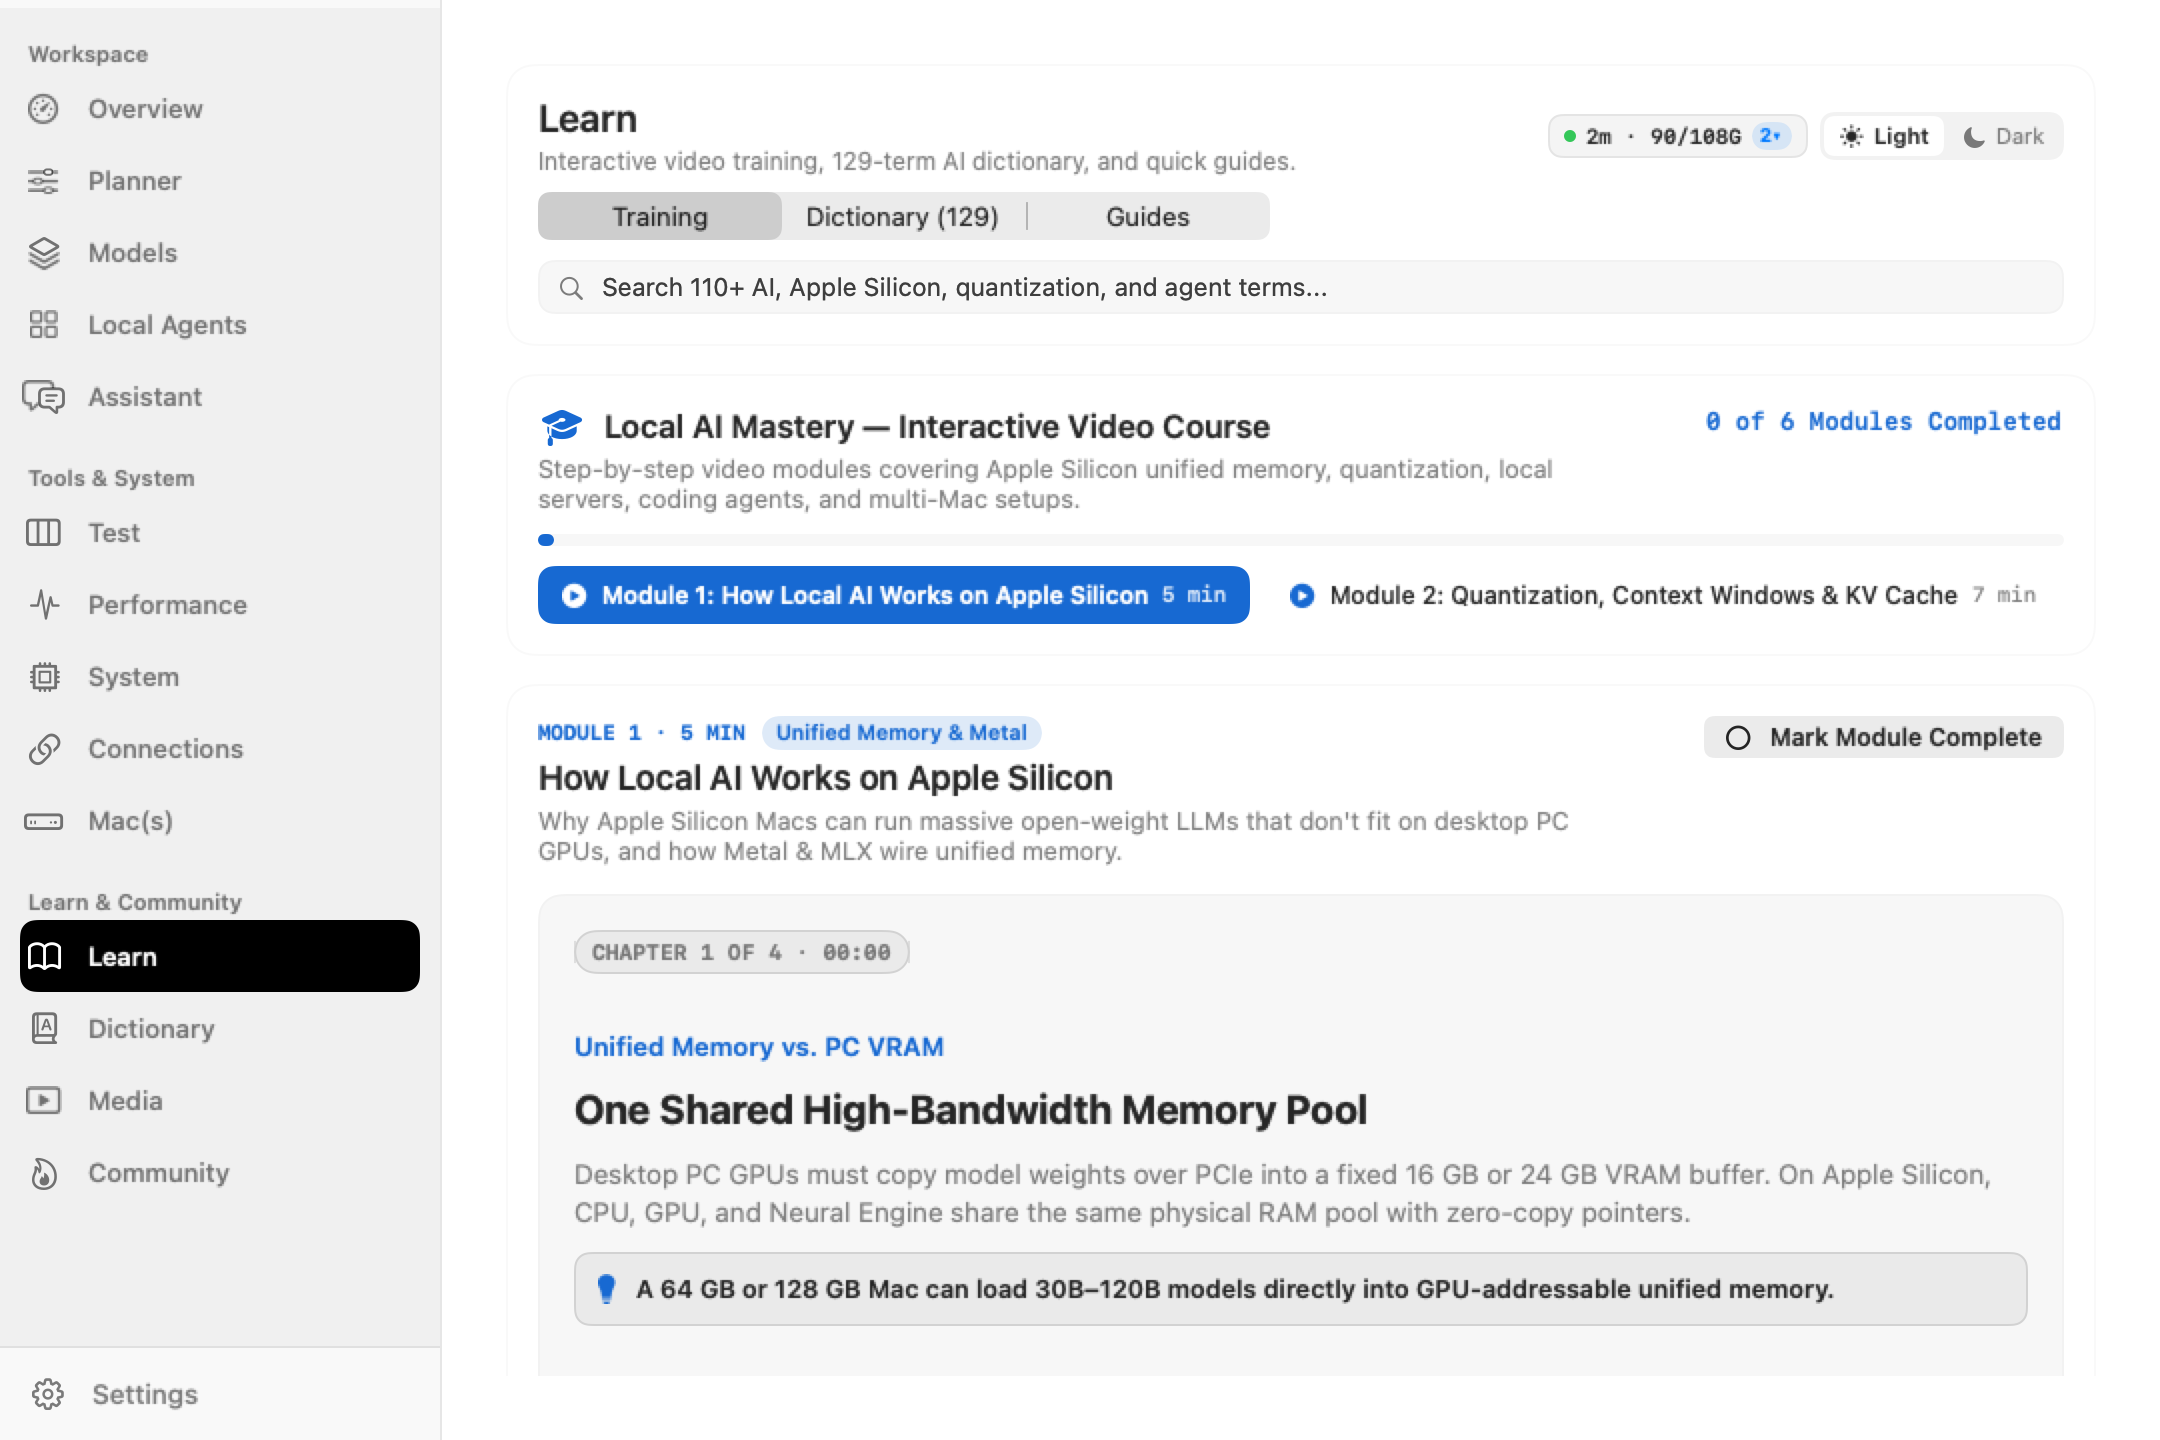
6 video modules, 129-term dictionary, quick guides
Built-in Apple Silicon local AI curriculum covering unified memory, quantization, KV cache sizing, and coding triads.
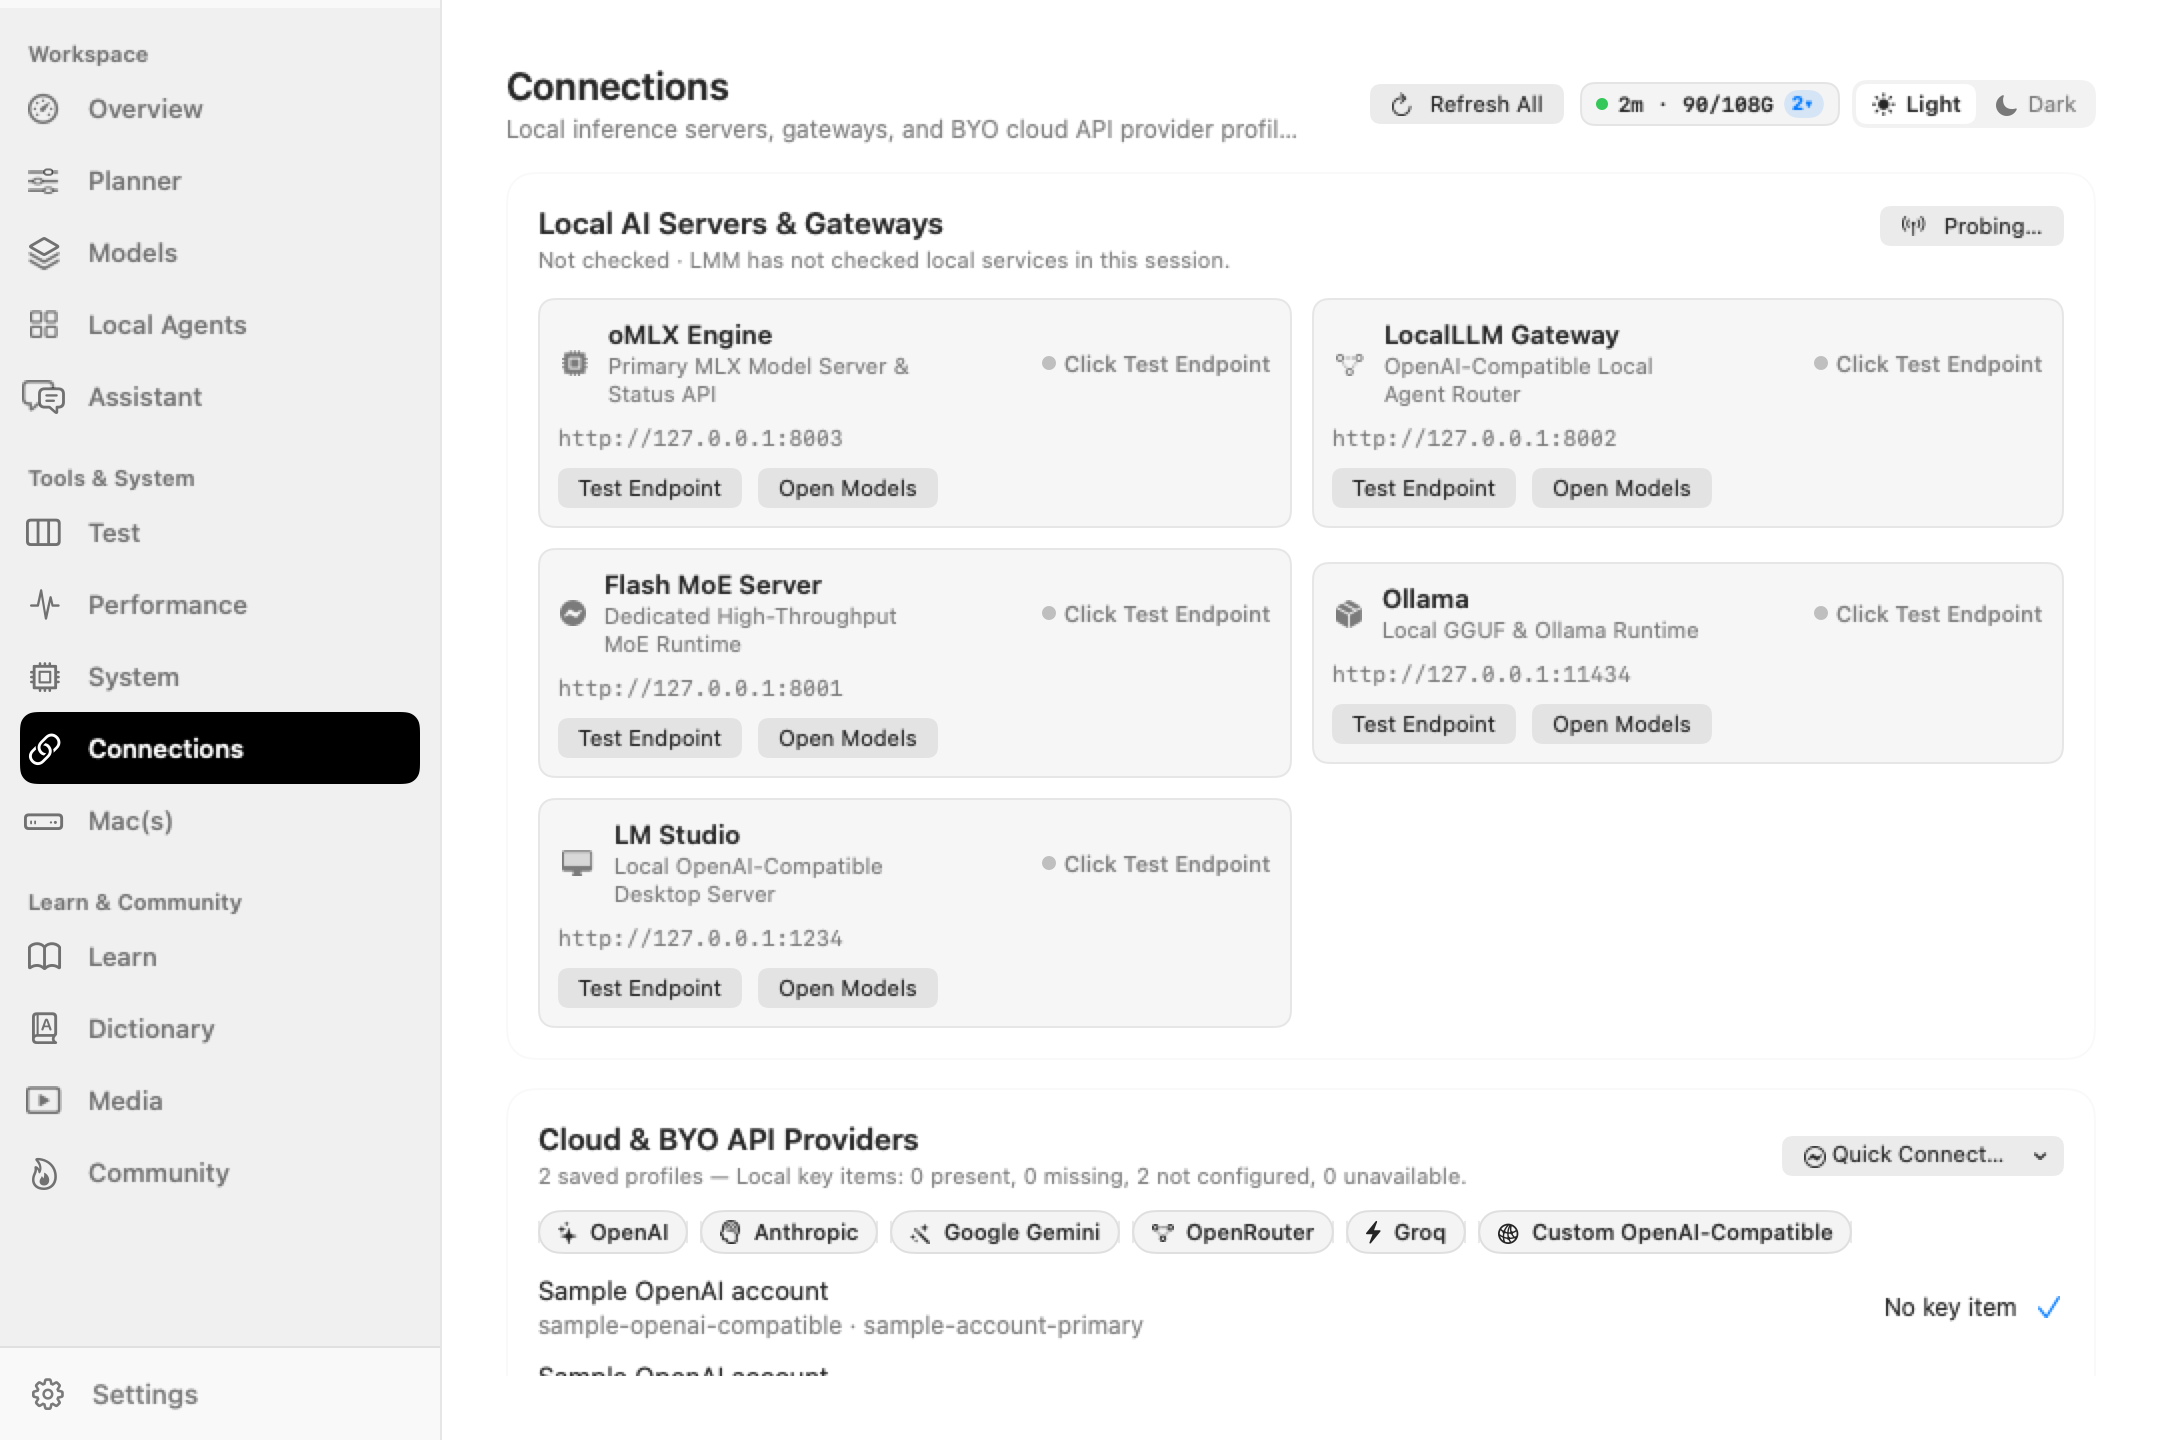
Local servers, endpoint tests, optional cloud profiles
See which local model servers are running on this Mac and test each endpoint before you route an app to it.
Monthly starts with a 3-day free trial and Annual starts with a 7-day free trial. One-time is charged at checkout with no trial. We email you before your first charge, with a link to cancel. To credit unused time automatically, upgrade from the app (Settings › License › Upgrade). Upgrades bought on the website without signing in are credited by support on request.
Launch offer20% off the first payment with code LAUNCH20
$7.96/monthRegular price $9.95
Includes a 3-day free trial. Launch price with LAUNCH20 on first payment. Upgrade from the app to credit unused days automatically.
$31.96/yearRegular price $39.95
Includes a 7-day free trial. Launch price with LAUNCH20 on first payment. Upgrade from the app to credit unused time automatically.
$95.96onceRegular price $119.95
One payment, no renewal and no trial; charged at checkout. Includes all 1.x updates. Adding Mac seats from the app credits what you already paid.
Purchases are paused while we finish launch checks. No payment can be taken right now.
Prices are in US dollars before applicable tax. Monthly starts with a 3-day free trial and Annual starts with a 7-day free trial. One-time is charged at checkout with no trial. LAUNCH20 discounts the first payment only. To credit unused time automatically, upgrade from the app (Settings › License › Upgrade). Upgrades bought on the website without signing in are credited by support on request. Already purchased? Recover your license by email.
Straight answers about fit, privacy and your license.
It depends on the task, the model, the context size and what else is using memory. LMM weighs all of it and rates how well each setup fits your hardware. On a smaller Mac it tells you honestly when a setup is Frustrating or Won’t fit, and what would help.
Context is how much text a model keeps in mind at once: your conversation, files and an app’s instructions. A bigger context needs more memory, which is why a model that fits at 32k may not fit at 128k.
LMM runs on any Mac with Apple silicon (M1 or later) and macOS 14 or later. Chip-specific estimates cover M1 through M4 today; on a newer chip, LMM still shows live memory and loaded-model readings and marks chip-based estimates as unavailable.
No. LMM requires an Apple silicon Mac running macOS 14 or later. Apple silicon (M1 or later) is supported. Intel Macs aren’t supported.
LMM explains every finding before anything changes. Safe fixes can be undone, and everything else waits for your approval. Prompts you send to models never pass through LMM’s servers. The optional Setup Assistant is the one exception: it sends your setup question through LMM’s server to OpenAI.
Monthly includes a 3-day free trial and renews monthly until you cancel. Annual includes a 7-day free trial and costs about a third of paying monthly. One-time is a single payment with no renewal and no trial, and includes all 1.x updates. To credit unused time automatically, upgrade from the app (Settings › License › Upgrade). Upgrades bought on the website without signing in are credited by support on request.
Monthly starts with a 3-day free trial and Annual starts with a 7-day free trial. One-time is charged at checkout with no trial. We email you before your first charge, with a link to cancel. All features are unlocked during a trial.
Each headless instance running LMM or the lmm-host daemon counts as one Mac seat in your plan, the same as a desktop or laptop. Choose a 2-Mac or 5-Mac plan under Pricing to cover multiple instances.
Yes, if you want it. Connect a cloud model you choose, ideally a low-cost one whose data policy you have read, and LMM writes out each step in plain words before anything runs. It’s optional, and LMM works without it.
To credit unused time automatically, upgrade from the app (Settings › License › Upgrade). Upgrades bought on the website without signing in are credited by support on request. Every first-time purchase also includes a 30-day money-back guarantee.
Free to download. Monthly starts with a 3-day free trial and Annual starts with a 7-day free trial. One-time is charged at checkout with no trial. Already a customer? Recover your license by email.